By hitmind.ai | Published 2026-10-15 | Updated 2026-10-15
A self hosted search console warehouse architecture should separate data collection, credential handling, and performance reporting. The goal is not merely to copy Google Search Console into a database. It is to preserve trustworthy evidence while controlling who can access queries, move data, and reproduce an SEO result.
The blueprint below combines documented Google export behavior with a proposed three-boundary evidence framework: collection, storage, and proof. It is a reference design—not a claim about HitMind’s infrastructure or a certification of regulatory compliance.
What does “self hosted” mean for Search Console data?
A self-hosted Search Console warehouse is an analytics environment whose storage, transformations, and access policies your organization operates. Google remains the source of search-performance data. You can control the downstream warehouse without running Search Console itself or assuming that every component must reside on-premises.
Choose between two collection paths:
| Path | Data flow | Important limitation |
|---|---|---|
| Native bulk export | GSC → BigQuery → customer-operated warehouse | Requires a Google Cloud landing zone |
| API extraction | GSC API → customer-operated collector → warehouse | Does not guarantee every detailed row |
Google’s native bulk export runs daily and avoids the daily row limit. The Search Analytics API supports historical extraction, but Google documents limits and warns that requesting page or query detail can lose data. Pagination alone is not proof of completeness. (support.google.com)
Recommended decision rule: use bulk export for ongoing coverage when policy permits BigQuery staging; use API extraction for historical backfill or a constrained deployment. Label their provenance separately rather than presenting them as equivalent sources.
How should the collection-to-warehouse pipeline work?
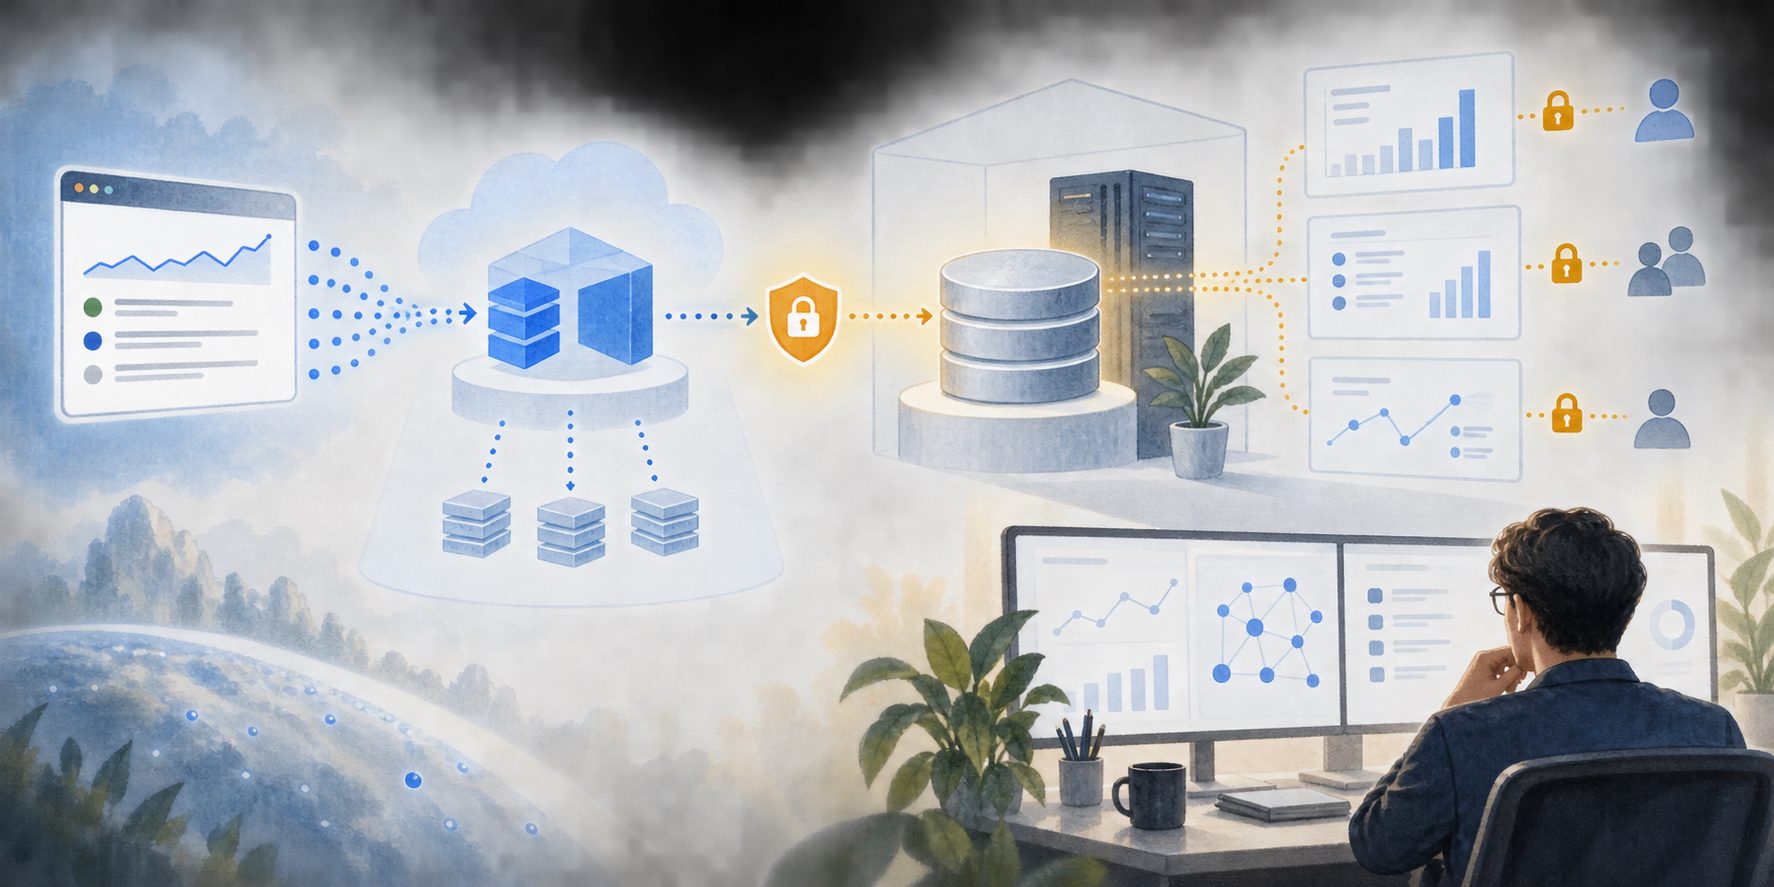
Use a customer-controlled landing zone, a revision-aware transfer job, and a separate reporting layer. Keep Google-managed export tables unchanged. Treat each exported date as a replaceable snapshot, not an append-only event stream. This design makes retries and corrections easier to reason about.
Search Console
  ├─ Daily bulk export → customer BigQuery dataset
  │                        ↓
  │                  revision-aware transfer
  │                        ↓
  └─ API backfill → separately labeled historical partitions
                           ↓
                customer-operated warehouse
                           ↓
                 restricted reporting views
Google supports exporting BigQuery data to Cloud Storage, including Parquet. A transfer worker can then load those files into your chosen warehouse; this downstream implementation is your responsibility. (docs.cloud.google.com)
For implementation:
- Have a property owner configure the bulk export.
- Choose the dataset location before collection starts.
- Preserve the exported schema.
- Validate each transferred partition before promoting it to reporting.
Bulk export does not backfill dates preceding setup; historical data requires the API or reports. Google also warns that changing export-table schemas can break collection. (support.google.com)
Use the full GSC export automation guide for the collection workflow.
How can credentials stay outside the reporting boundary?
Separate the identities that configure exports, transfer data, and read reports. For Google Cloud access from an external worker, Workload Identity Federation can replace downloaded service-account keys with federated access and short-lived credentials. That reduces persistent-key exposure; it does not eliminate every security risk. (docs.cloud.google.com)
Google’s setup instructions grant its export principal BigQuery Job User and BigQuery Data Editor. Those permissions belong to the export mechanism—not automatically to analysts, dashboards, or content vendors. (support.google.com)
Apply this proposed access model:
| Identity | Intended access |
|---|---|
| Property owner | Configure Search Console export |
| Google export principal | Write the designated landing dataset |
| Transfer worker | Read landing data; write destination partitions |
| Analyst | Read approved reporting views |
| External reviewer | Receive an approved evidence extract |
Restrict federation to the intended workload identity. Keep credentials out of source repositories, browser payloads, prompt inputs, and application logs.
Keyless is narrower than “zero leakage.” Query text, exported files, and access tokens still need protection. The GSC service-account permissions guide complements this identity separation.
How do you prevent retries from inflating results?
Replace a complete date partition when its source revision changes. Do not append every transfer attempt or discard repeated dimension rows as duplicates. Google explains that exported rows can share keys and should be aggregated; repeated keys can represent legitimate increments. (support.google.com)
Track a transfer manifest containing:
- Property identifier and source table.
- Source date and
epoch_version. - Extraction timestamp and destination snapshot identifier.
- Row count, click total, impression total, and validation status.
ExportLog records successful exports and revision versions, but not failures. Its dates use Pacific Time. Monitor missing expected dates separately from successful-job records. (support.google.com)
Illustrative acceptance fixture—not customer data:
| Input | Expected stored clicks |
|---|---|
| Initial partition: 100 clicks | 100 |
| Same partition transferred again | 100 |
| Revised partition: 103 clicks | 103 |
| Transfer interrupted before promotion | Previous validated total |
This fixture distinguishes legitimate source aggregation from accidental replay inflation. Publish the destination snapshot only after validation, and retain enough metadata to explain which revision produced a report.
What makes warehouse metrics defensible?
A defensible metric preserves its source grain, privacy flags, filters, and calculation. Keep property-level and URL-level datasets separate. Preserve anonymized-query indicators rather than attempting to reconstruct hidden search terms. Google’s schema includes anonymized rows without readable query text and different position fields for each grain. (support.google.com)
For supported position reporting, calculate weighted metrics:
CTR = SUM(clicks) / SUM(impressions)

Property average position =
  SUM(sum_top_position) / SUM(impressions) + 1

URL average position =
  SUM(sum_position) / SUM(impressions) + 1
Guard against zero denominators. Do not average row-level averages. These position calculations follow Google’s documented formulas. (support.google.com)
Define retention across every copy: BigQuery, transfer files, warehouse partitions, backups, and evidence extracts. Google’s export tables retain data indefinitely by default, subject to project or organization settings; configure partition expiration deliberately. (support.google.com)
For cost control, require date-filtered reporting and record storage, transfer, and query usage separately. A dashboard that looks accurate but cannot identify its source date, grain, or revision should not serve as enterprise evidence.
How does the three-boundary framework support SEO proof?
The three-boundary framework separates authority to collect, authority to retain, and authority to make a performance claim. Its distinctive rule is simple: an SEO result should be reproducible from an approved evidence package without giving the reviewer collection credentials or unrestricted warehouse access.
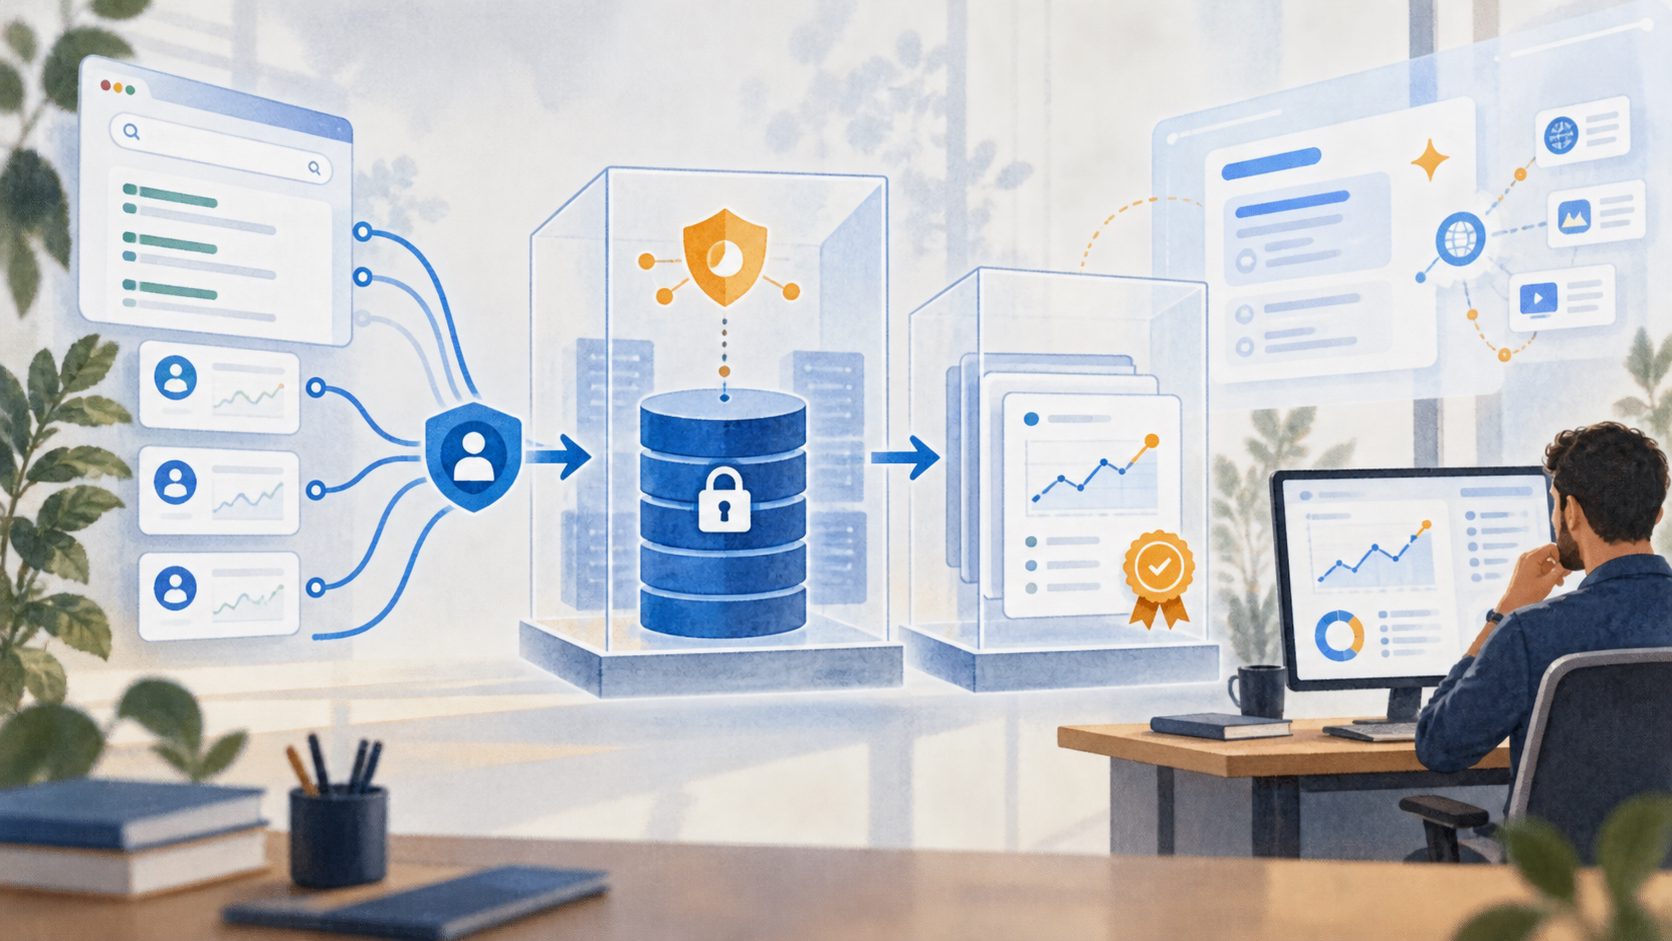
A proposed evidence package contains:
- Property and article URL.
- Publication date and measurement window.
- Source snapshot and transformation version.
- Device, country, and search-type filters.
- Clicks, impressions, comparison values, and completeness flags.
HitMind measures results using the customer’s own Google Search Console data. After an article has been live for 28 days, it provides a receipt reporting increases or decreases. That measurement principle does not establish a particular warehouse integration or keyless implementation. (hitmind.ai)
For enterprise evaluation, require the receipt to disclose its scope and separate observed change from causal attribution. Use the GSC-validated SEO proof-of-concept template to structure that review.
Frequently asked questions
Can native bulk export write directly to an on-premises warehouse?
No. Search Console’s native bulk export targets BigQuery. A customer-operated warehouse requires a downstream transfer, or a separate API-based collection path. (support.google.com)
Can API backfill recover every historical query?
Do not assume so. Google documents extraction limits and potential data loss when requesting detailed page or query dimensions. Historical API coverage should carry its own completeness qualifications. (developers.google.com)
Does this architecture make a deployment compliant?
No architecture diagram establishes compliance. Treat this blueprint as an engineering proposal requiring review of access, residency, retention, contracts, and operational evidence. Approve those controls before exposing production data or declaring the warehouse suitable for a regulated workload.