By hitmind.ai | Published 2026-09-28 | Updated 2026-09-28
To understand how to fix discovered currently not indexed, start with the status itself: Google knows the URL exists but has not crawled it yet. The solution is usually to improve crawl accessibility and priority—not to keep pressing “Request indexing.”
This guide provides a step-by-step fix, a SaaS-specific diagnostic framework, and a method for measuring whether the affected URL group is recovering.
What Does “Discovered—Currently Not Indexed” Mean?
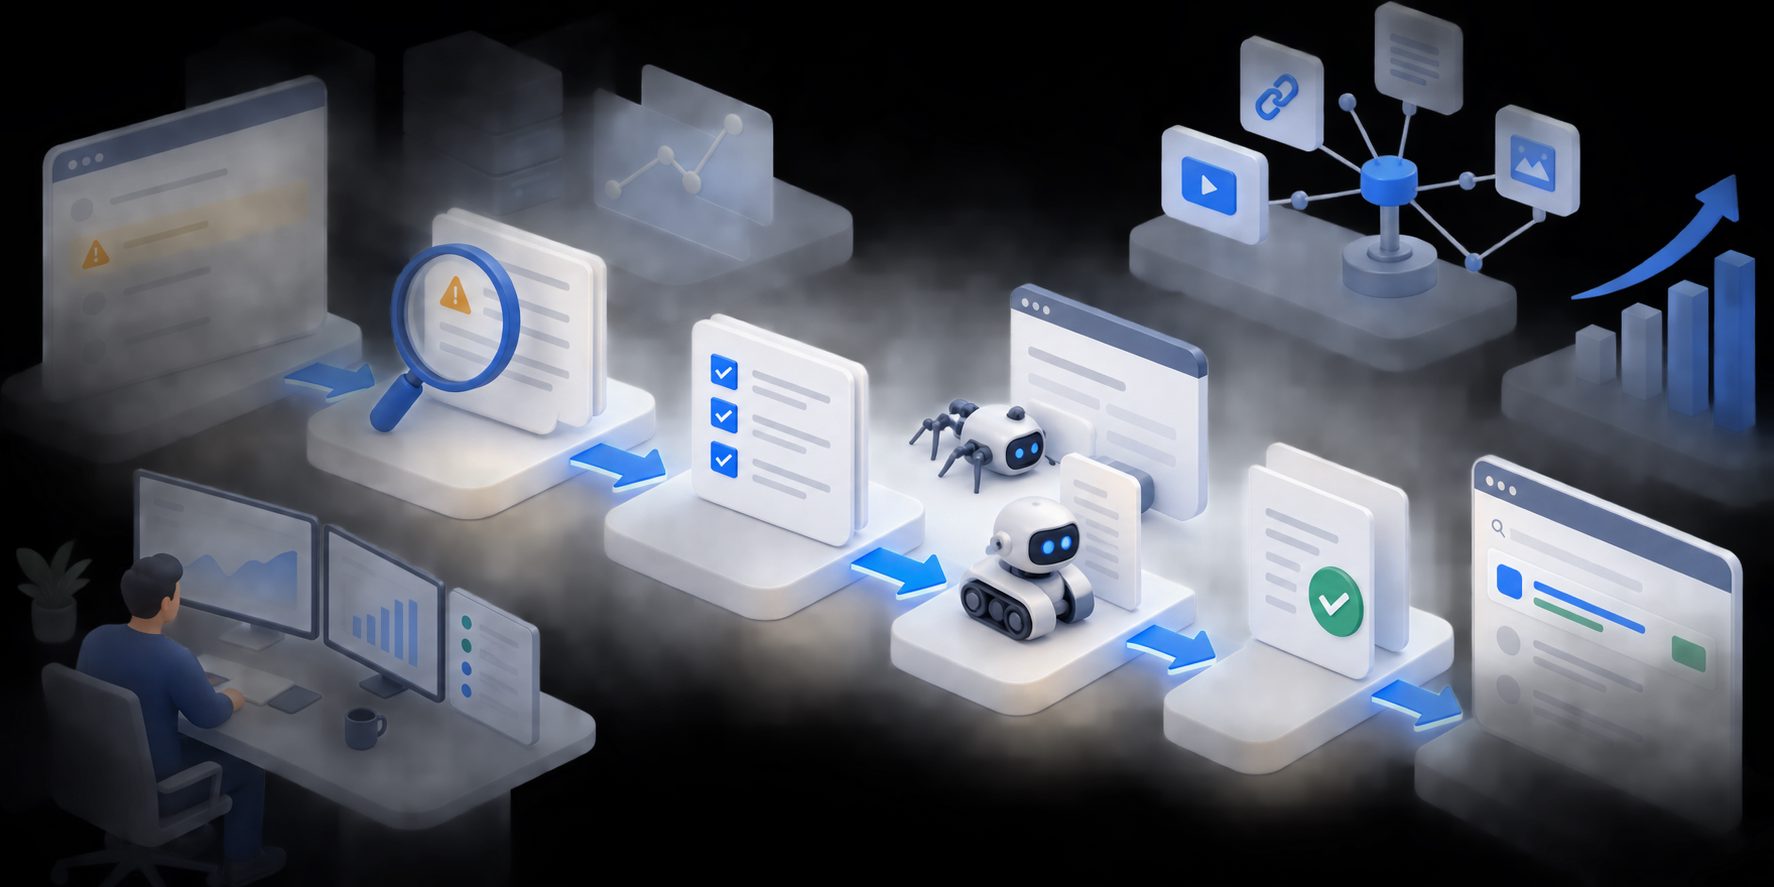
“Discovered—currently not indexed” means Google found the URL through a sitemap, internal link, or another source, but has not yet fetched it. Because no crawl has occurred, Google has not fully evaluated the page’s content or selected it for the index.
This differs from “Crawled—currently not indexed,” where Googlebot has already visited the page. According to the Google Search Console Page Indexing documentation, non-indexed URLs are not automatically errors, and site owners should not expect every known URL to appear in Google. (support.google.com)
| GSC status | What happened | Primary focus |
|---|---|---|
| Discovered—currently not indexed | URL found, not crawled | Crawl access, priority, capacity |
| Crawled—currently not indexed | URL fetched, not indexed | Content value, duplication, canonicalization |
| Blocked by robots.txt | Crawl explicitly restricted | Robots.txt rules |
| Duplicate or alternate page | Another URL may represent the content | Canonical signals |
How to Fix Discovered Currently Not Indexed
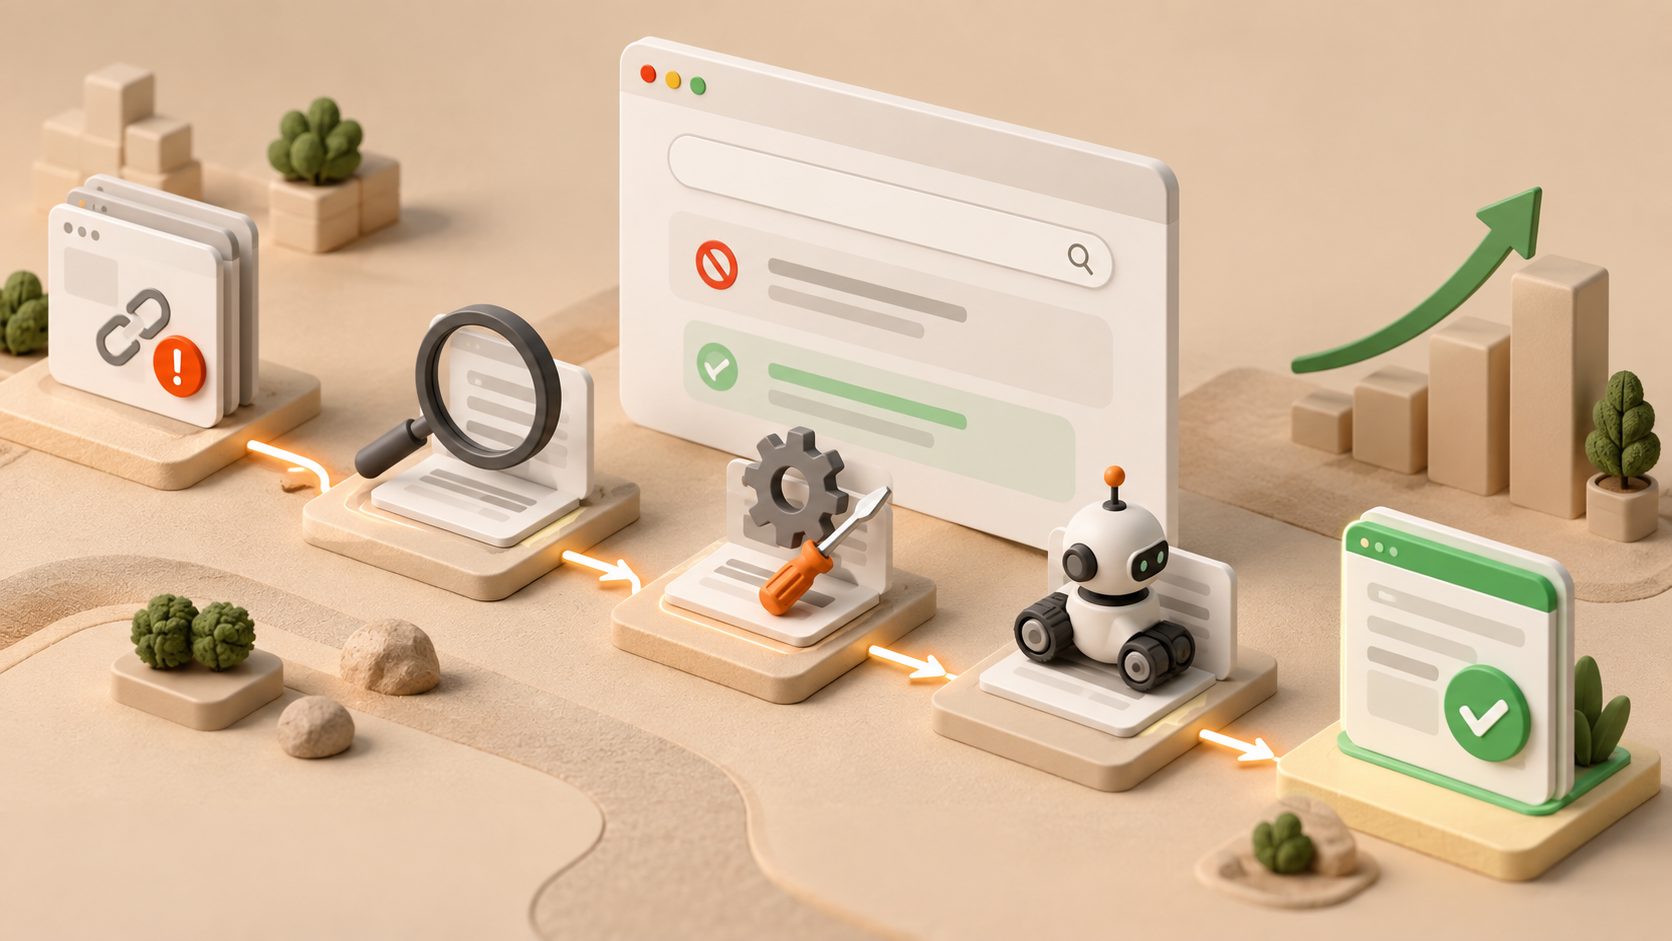
For one important page, confirm that it returns a valid response, is indexable, and has a self-referencing canonical. Then add internal links, include it in the XML sitemap, and request indexing once. For a large URL group, diagnose the shared template or crawl-priority problem before submitting individual pages.
Follow these steps in order:
- Inspect representative URLs in GSC. Check the reported discovery source, declared canonical, indexing permission, and sitemap inclusion.
- Run a live URL test. Confirm that Googlebot can access the page and that the server returns HTTP 200.
- Check robots and meta directives. Remove accidental
Disallow,noindex, authentication, or firewall restrictions. - Add crawlable internal links. Link from indexed product, feature, category, or content-hub pages using standard HTML anchors.
- Clean the XML sitemap. Include only canonical, indexable URLs that return 200 responses.
- Remove crawl traps. Control parameter URLs, internal search pages, duplicate archives, and unnecessary tag combinations.
- Check server capacity. Investigate 5xx errors, timeouts, slow responses, and Googlebot throttling.
- Request indexing once. Use it for a small number of priority pages, then monitor instead of repeatedly resubmitting.
Google states that crawl requests may take from several days to several weeks and do not guarantee inclusion. Repeated requests for the same URL will not make crawling faster. (developers.google.com)
Which Cause Should You Investigate First?
Prioritize causes by scope. One affected URL usually calls for page-level inspection. Hundreds of URLs sharing a directory, template, or publication date point to a systemic issue such as weak internal linking, URL inflation, rendering overhead, or limited server capacity.
Use this original Crawl Priority Score to triage URL groups. It is an operational framework, not a Google metric. Give each factor 0, 1, or 2 points:
- Accessibility: blocked or unreliable (0), inconsistent (1), clean HTTP 200 (2)
- Internal prominence: orphaned (0), one deep link (1), several relevant indexed links (2)
- URL uniqueness: duplicate (0), overlapping (1), distinct purpose (2)
- Sitemap accuracy: absent or misleading (0), inconsistent (1), canonical and current (2)
- Server health: frequent failures (0), occasional latency (1), stable responses (2)
Interpret the total:
| Score | Recommended action |
|---|---|
| 0–3 | Fix technical access and URL inventory first |
| 4–6 | Strengthen links, uniqueness, and sitemap signals |
| 7–8 | Request indexing for priority URLs and monitor |
| 9–10 | Wait unless the issue persists across a meaningful URL group |
This scoring model prevents teams from rewriting good pages when the real bottleneck is crawl access—or optimizing servers when the URLs should instead be consolidated.
How Should SaaS Sites Improve Crawl Priority?
SaaS sites should concentrate crawl signals on pages that answer distinct buyer questions. Feature variations, integration pages, comparison templates, localization, and programmatic landing pages can create more URLs than the site’s navigation and authority can support.
Start by linking each important page from a relevant indexed hub. A new integration page, for example, should be reachable from the integrations directory and supporting documentation—not only listed in a sitemap.
Then review common sources of URL waste:
- Filter and sorting parameters
- Staging or preview URLs
- Empty tag and author archives
- Duplicate feature pages targeting the same intent
- JavaScript routes without crawlable
<a href>links - Trailing-slash, protocol, or hostname variants
- Translated pages with inconsistent canonical or
hreflangsignals
Google notes that unnecessary parameter and faceted URLs can consume crawling resources and slow the discovery of useful pages. Its crawling guidance also recommends examining robots rules, sitemap coverage, serving capacity, redirect chains, and server logs. (developers.google.com)
For overlapping SaaS pages, use a Search Console cannibalization audit workflow to decide whether to differentiate, consolidate, or redirect them.
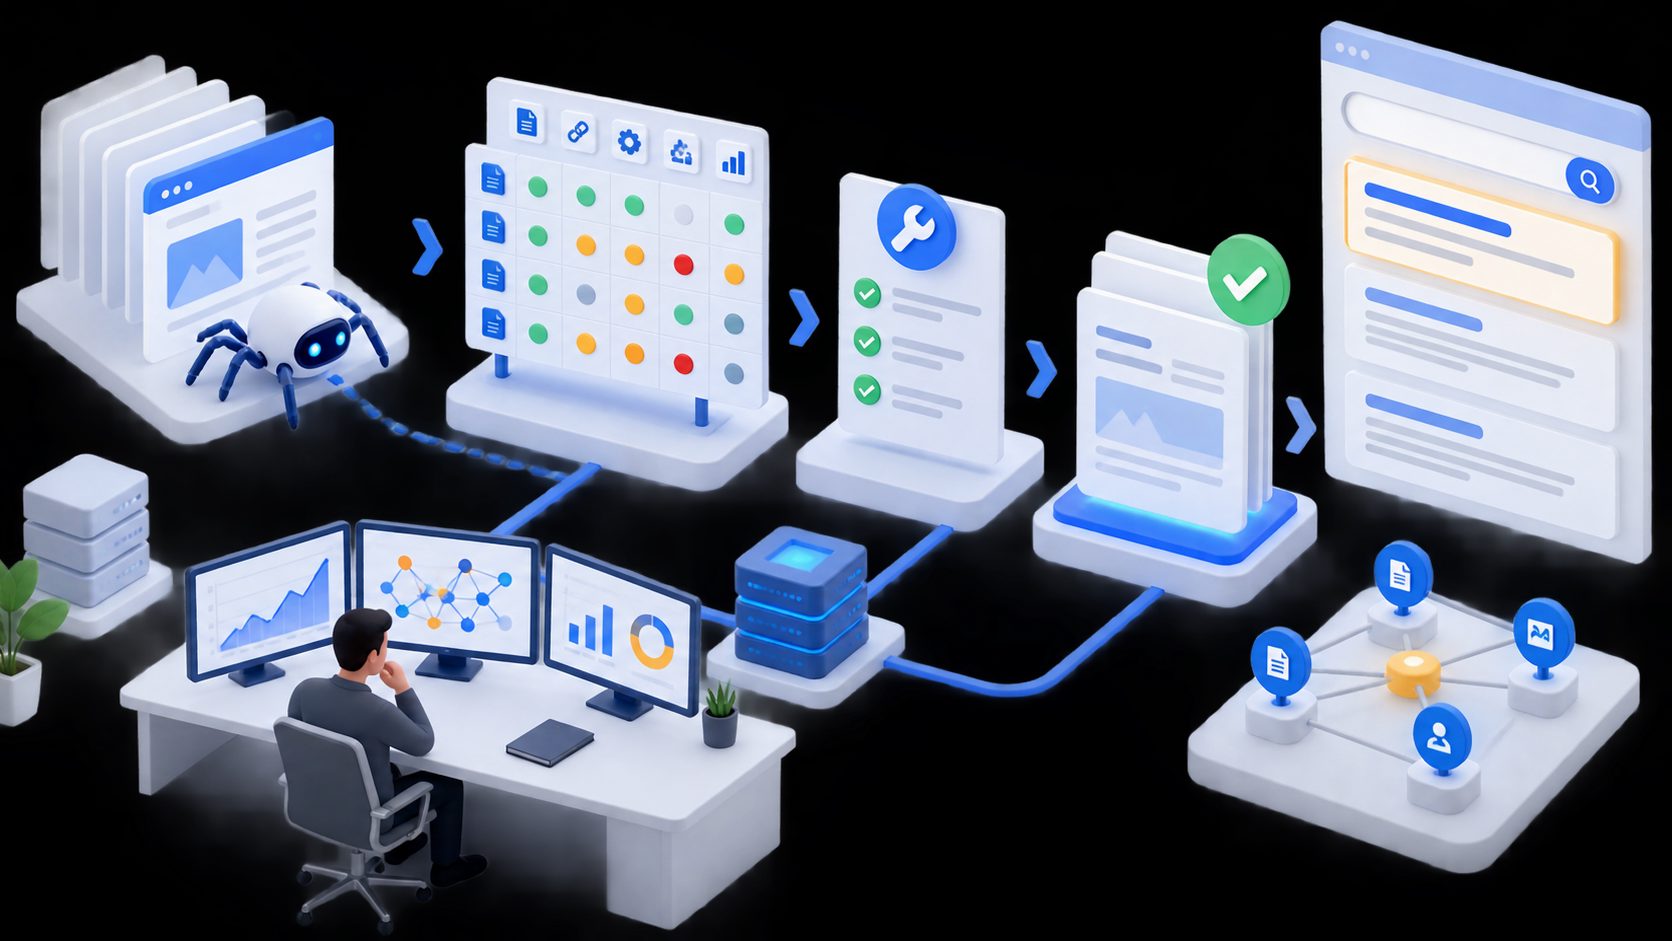
Do Sitemaps and Request Indexing Solve the Problem?
Sitemaps support discovery, while request indexing places an individual URL into a crawl queue. Neither mechanism guarantees crawling, indexing, or rankings. They work best after technical access, canonicalization, internal linking, and page value have been addressed.
A clean sitemap should contain URLs that:
- Return HTTP 200
- Are allowed to be crawled and indexed
- Use the preferred canonical version
- Provide meaningful standalone value
- Have accurate
lastmoddates when materially updated
Google explicitly says that a sitemap can help it discover URLs but does not guarantee that every submitted page will be crawled or indexed. (developers.google.com)
Avoid resubmitting unchanged sitemaps several times per day. For small sites, navigation and contextual internal links often communicate importance more effectively than adding more sitemap files.
How Do You Verify That the Fix Worked?
Measure recovery by URL group rather than checking isolated pages every day. Export the affected URLs before making changes, classify them by template or directory, and compare their status after Google has had time to recrawl the site.
Track these four metrics:
- Number of URLs remaining in “Discovered—currently not indexed”
- Number moving to “Crawled—currently not indexed”
- Number becoming indexed
- Googlebot requests and server errors for the affected directory
Moving from “discovered” to “crawled” proves that the crawl bottleneck changed, but it does not guarantee indexing. If URLs are crawled and then excluded, shift the investigation toward duplication, search-intent overlap, canonical selection, and content usefulness.
For scalable monitoring, connect indexing checks to a Search Console feedback-loop framework. Once pages begin receiving impressions, separate branded and non-branded GSC performance so indexing progress is not mistaken for meaningful organic growth.
Common Questions
How long does “Discovered—currently not indexed” last?
There is no fixed deadline. Google says crawling can take several days to several weeks, depending on factors such as site quality, crawl demand, server capacity, and the importance of the URL. Persistent patterns across many important pages deserve investigation.
Should I request indexing every day?
No. Request indexing once after confirming that the URL is accessible, canonical, useful, and internally linked. Google states that repeated submissions do not accelerate crawling.
Is this status always caused by crawl budget?
No. Crawl budget is most relevant to large or rapidly changing sites. Small SaaS sites can see the status because of weak internal links, a new domain, server instability, duplicate URLs, or pages that appear unimportant within the site architecture.
Can content quality matter before Google crawls the page?
Google cannot fully evaluate an uncrawled page, but site-wide patterns can influence crawl scheduling. Large groups of repetitive, thin, or low-demand URLs may reduce the priority assigned to similar new URLs.
Can an SEO audit identify the likely cause?
A technical audit can surface robots restrictions, sitemap inconsistencies, canonical conflicts, broken internal links, status-code problems, and URL duplication. The free SEO audit available through HitMind requires no registration or payment; signing up is free too, after which HitMind drafts articles from brand facts you approve and delivers them to WordPress as drafts.