By hitmind.ai | Published 2026-10-04 | Updated 2026-10-04
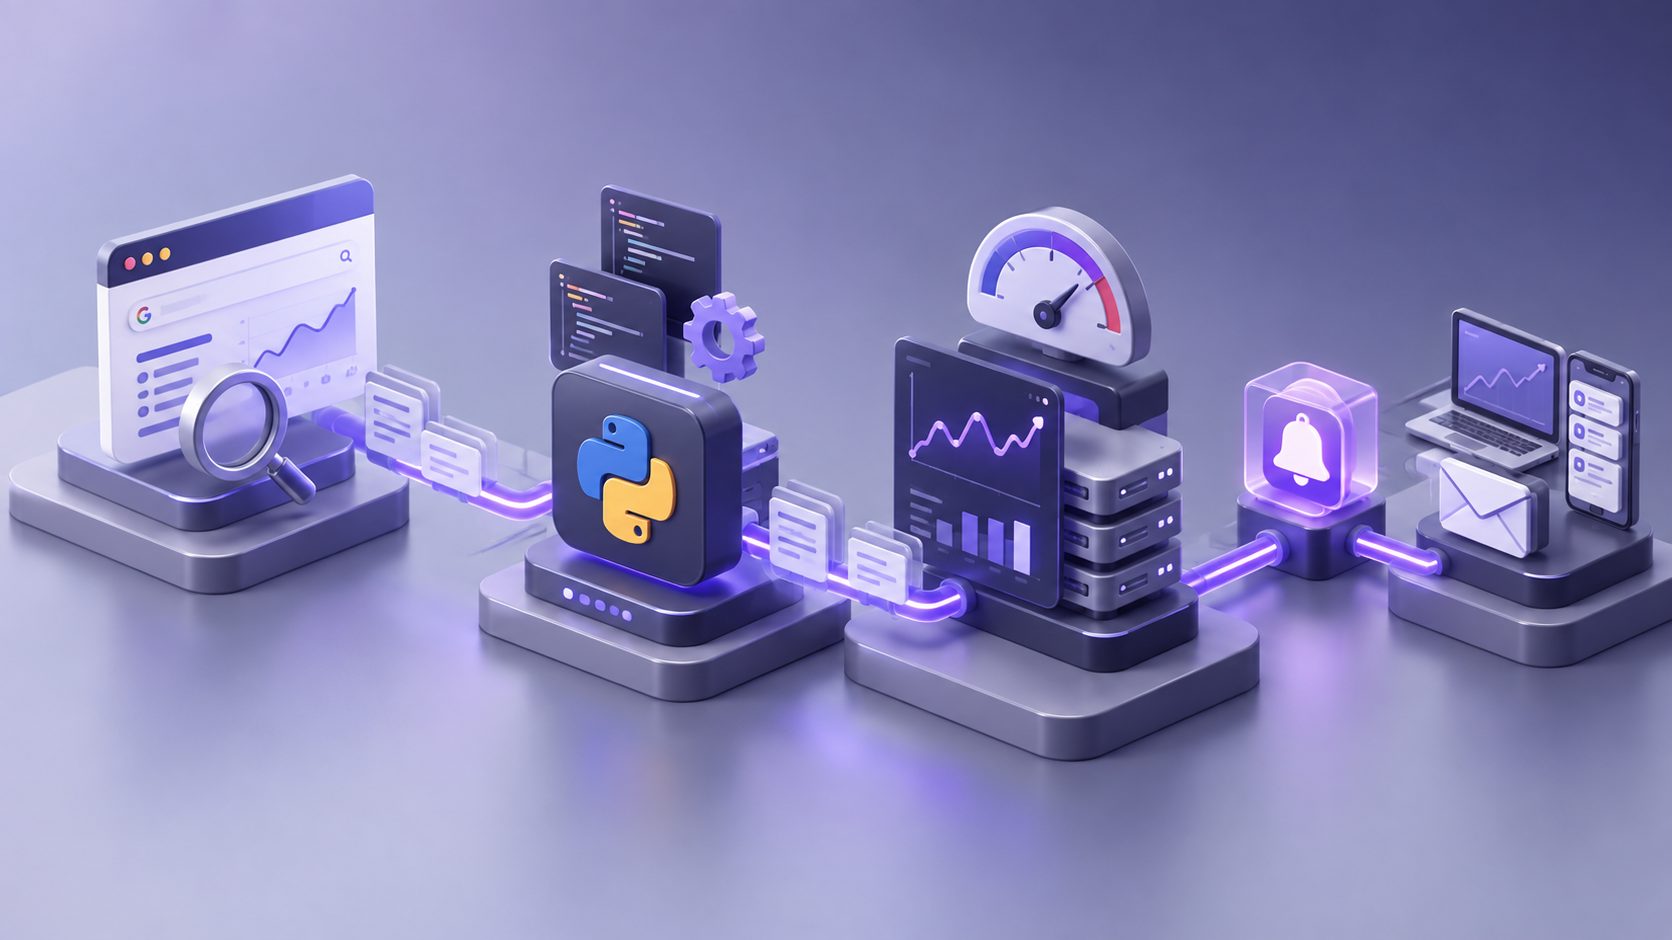
A reliable Google Search Console API rate limit monitoring script should do more than retry failed requests. It must pace traffic before limits are reached, classify quota errors, record request context, stop retrying unrecoverable daily-limit failures, and notify an operator when data freshness is at risk.
This guide provides a reusable Python pattern plus a monitoring architecture for scheduled Search Analytics exports, URL inspections, and multi-property SEO reporting.
What Limits Does the Search Console API Enforce?
Search Console applies different quotas to Search Analytics, URL Inspection, and other resources. Rate limits may be scoped by site, user, or Google Cloud project, so staying below one published ceiling does not guarantee that every request will succeed.
According to Google’s Search Console API usage limits, the principal published limits as of October 4, 2026 are: (developers.google.com)
| API resource | Scope | Published limit |
|---|---|---|
| Search Analytics | Per site | 1,200 queries per minute |
| Search Analytics | Per user | 1,200 queries per minute |
| Search Analytics | Per project | 40,000 per minute; 30 million per day |
| URL Inspection | Per site | 600 per minute; 2,000 per day |
| URL Inspection | Per project | 15,000 per minute; 10 million per day |
| Other resources | Per user | 20 per second; 200 per minute |
| Other resources | Per project | 100 million per day |
Search Analytics also has undocumented numeric load quotas measured over short-term 10-minute and long-term one-day windows. Queries become more expensive when they cover long date ranges or group and filter by both page and query.
Why Is Request Counting Alone Insufficient?
Request counting detects traffic velocity, but it cannot fully predict Search Analytics load consumption. A one-day query grouped by date is operationally different from a six-month query segmented by page and query, even though both count as one API call.
A production monitor should therefore track four signals:
- Velocity: Calls made during rolling second, minute, and day windows.
- API outcome: HTTP status, Google error reason, latency, and retry count.
- Query shape: Date span, dimensions, filters, property, and search type.
- Freshness: Time since the last successful data checkpoint.
This is the quota envelope model: monitor not only how many requests you send, but also how expensive they are and whether failures are delaying usable data.
For an optional internal load proxy, calculate:
load_score = date_range_days × (1 + page_dimension + query_dimension + combined_penalty)
This is not Google’s quota formula. It is an operational score for comparing your own jobs and identifying queries that should be split into smaller date windows.
How Do You Build the Monitoring Script?
The safest pattern combines a rolling local throttle with structured error handling. The script below leaves 25% headroom under a configured minute limit, emits JSON logs, retries transient failures with jitter, and immediately escalates ambiguous or daily quota exhaustion.
import collections
import json
import os
import random
import time
import urllib.request

from google.oauth2 import service_account
from googleapiclient.discovery import build
from googleapiclient.errors import HttpError

SCOPES = ["https://www.googleapis.com/auth/webmasters.readonly"]
MAX_RPM = int(os.getenv("GSC_MAX_RPM", "900"))
WEBHOOK_URL = os.getenv("GSC_ALERT_WEBHOOK")
timestamps = collections.deque()

TRANSIENT_REASONS = {
    "rateLimitExceeded",
    "userRateLimitExceeded",
    "servingLimitExceeded",
    "concurrentLimitExceeded",
}
STOP_REASONS = {"dailyLimitExceeded", "quotaExceeded", "limitExceeded"}


def emit(event, **fields):
    print(json.dumps({"event": event, "time": time.time(), **fields}))


def alert(message):
    emit("alert", message=message)
    if WEBHOOK_URL:
        request = urllib.request.Request(
            WEBHOOK_URL,
            data=json.dumps({"text": message}).encode(),
            headers={"Content-Type": "application/json"},
        )
        urllib.request.urlopen(request, timeout=10)


def throttle():
    now = time.monotonic()
    while timestamps and now - timestamps[0] >= 60:
        timestamps.popleft()

    if len(timestamps) >= MAX_RPM:
        delay = 60 - (now - timestamps[0]) + random.uniform(0.1, 1.0)
        emit("throttled", sleep_seconds=round(delay, 2))
        time.sleep(delay)

    timestamps.append(time.monotonic())


def error_details(error):
    try:
        payload = json.loads(error.content.decode("utf-8"))
        reason = payload["error"]["errors"][0].get("reason", "unknown")
    except (ValueError, KeyError, IndexError, AttributeError):
        reason = "unknown"
    return int(error.resp.status), reason


def execute_with_monitoring(request, context, attempts=6):
    for attempt in range(attempts):
        throttle()
        started = time.monotonic()

        try:
            response = request.execute()
            emit(
                "success",
                latency_ms=round((time.monotonic() - started) * 1000),
                **context,
            )
            return response
        except HttpError as error:
            status, reason = error_details(error)
            emit("api_error", status=status, reason=reason,
                 attempt=attempt + 1, **context)

            if reason in STOP_REASONS:
                alert(f"GSC quota stopped job: {reason}; context={context}")
                raise

            retryable = status in {429, 500, 502, 503, 504}
            retryable = retryable or reason in TRANSIENT_REASONS
            if not retryable or attempt == attempts - 1:
                alert(f"GSC request failed: {status}/{reason}; context={context}")
                raise

            delay = min(120, 2 ** attempt) + random.uniform(0, 1)
            time.sleep(delay)


credentials = service_account.Credentials.from_service_account_file(
    os.environ["GOOGLE_APPLICATION_CREDENTIALS"],
    scopes=SCOPES,
)
service = build("searchconsole", "v1",
                credentials=credentials, cache_discovery=False)

site_url = "sc-domain:example.com"
body = {
    "startDate": "2026-10-01",
    "endDate": "2026-10-01",
    "dimensions": ["query"],
    "rowLimit": 25000,
}

request = service.searchanalytics().query(siteUrl=site_url, body=body)
data = execute_with_monitoring(
    request,
    {"property": site_url, "resource": "searchanalytics", "days": 1},
)
Replace the example property and ensure the service account has access to it. Search Console requests require OAuth 2.0 authorization; read-only collection should use the narrow read-only scope. (developers.google.com)
How Should Quota Errors Be Handled?
Quota-related failures can arrive as HTTP 403 or 429 responses. The response reason is therefore more useful than the status code alone.
Google documents reasons including rateLimitExceeded, userRateLimitExceeded, quotaExceeded, dailyLimitExceeded, and concurrentLimitExceeded. A 429 rateLimitExceeded response represents too many requests within a time window. (developers.google.com)
Use this decision table:
| Failure type | Correct response |
|---|---|
| Short-term rate limit | Exponential backoff with random jitter |
| Daily limit | Stop the job and resume after the quota window resets |
| Search Analytics load quota | Wait at least 15 minutes, then reduce date ranges or dimensions |
| 500 or 503 response | Retry with a capped delay |
| Authentication failure | Refresh credentials or alert; do not retry indefinitely |
Never retry every failure immediately. Synchronized workers can create a retry storm that turns a temporary error into a prolonged outage.
What Changes for Multiple Workers or Properties?
An in-process deque protects only one worker. If several containers, scheduled functions, or customer connections share a Cloud project, use a distributed token bucket in Redis, PostgreSQL, or another atomic store.
Store counters by the scope that can actually fail:
project + minute
OAuth user + minute
Search Console property + minute
Search Console property + day + API resource
Add a durable checkpoint after each completed date-property-search-type partition. That lets the next run replay only missing slices rather than repeatedly querying an entire historical range.
For larger exports, combine this design with a reliable GSC-to-BigQuery synchronization workflow and pagination practices for exporting all Search Console queries.
How Should Cloud Monitoring Complement the Script?
Application logs explain which job failed; Google Cloud metrics show project-wide API behavior that an individual worker cannot see. Use both layers rather than treating either as the single source of truth.
Google Cloud exposes API request counts, errors, latency, and consumer quota metrics. These metrics can feed dashboards and alert policies in Cloud Monitoring. (docs.cloud.google.com)
Create alerts for:
- Any quota-exceeded event.
- A sustained increase in 403 or 429 responses.
- More than 75% of a known rate quota.
- No successful checkpoint within the expected sync window.
- An unusual increase in requests per exported row.
The final alert is especially valuable: rising calls per row often reveals overlapping jobs, broken pagination, or repeated extraction of unchanged data.
Where Does This Fit in an SEO Data Pipeline?
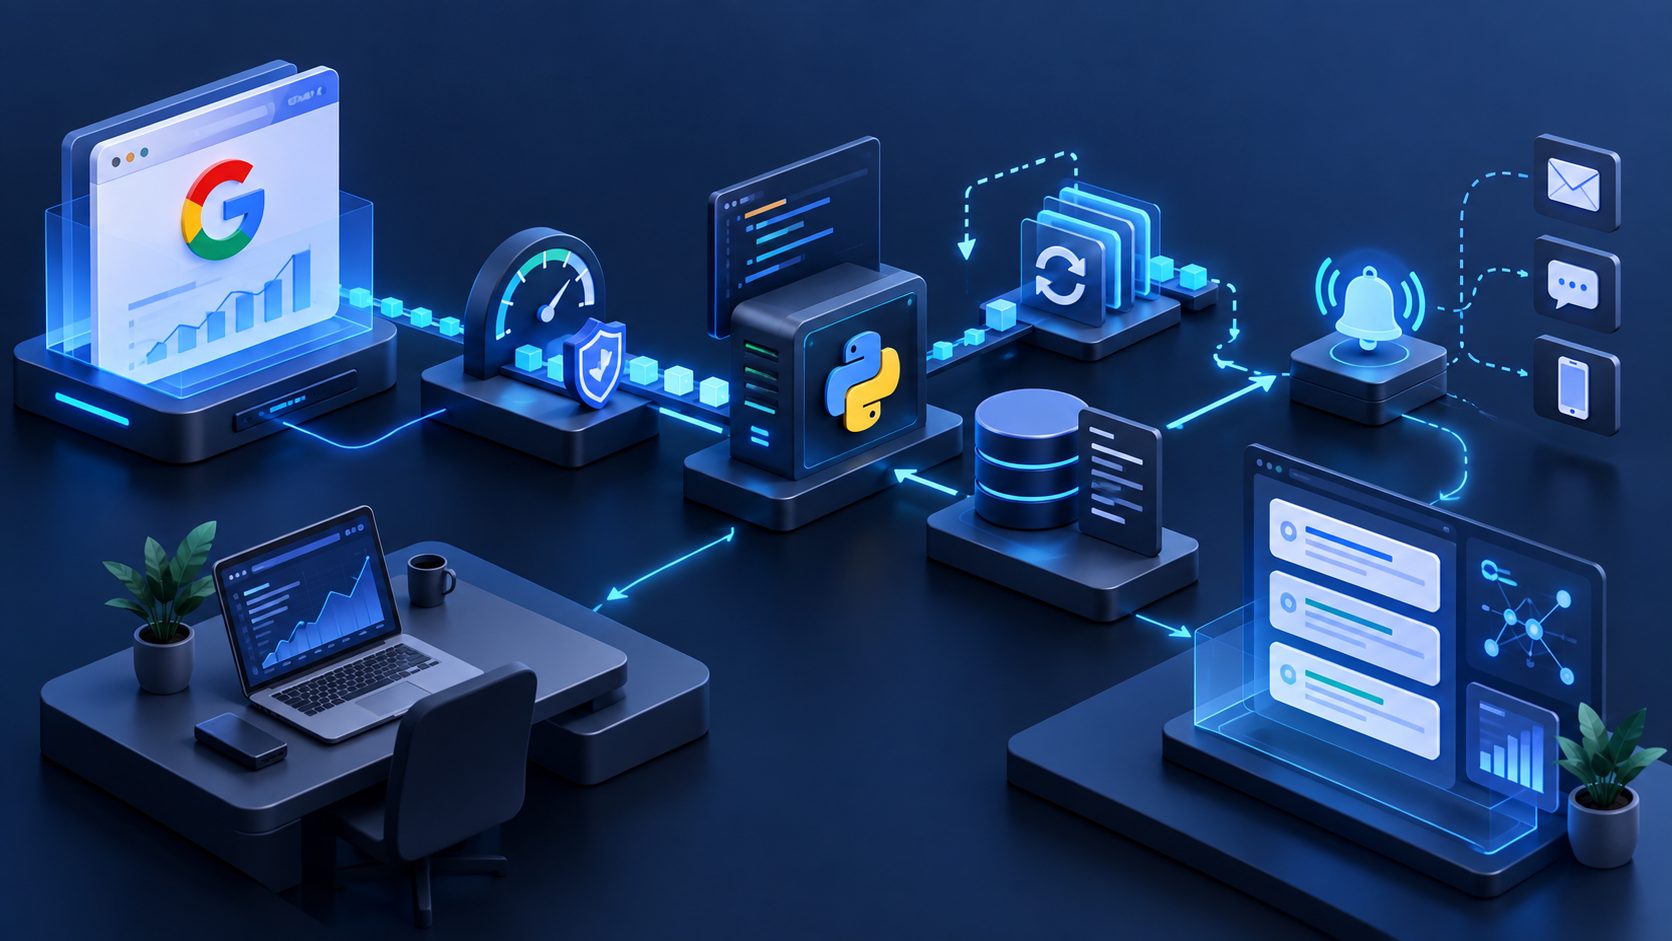
Rate-limit handling belongs between extraction scheduling and storage—not inside reporting dashboards. Dashboards should read stable tables rather than call Search Console interactively whenever a user changes a filter.
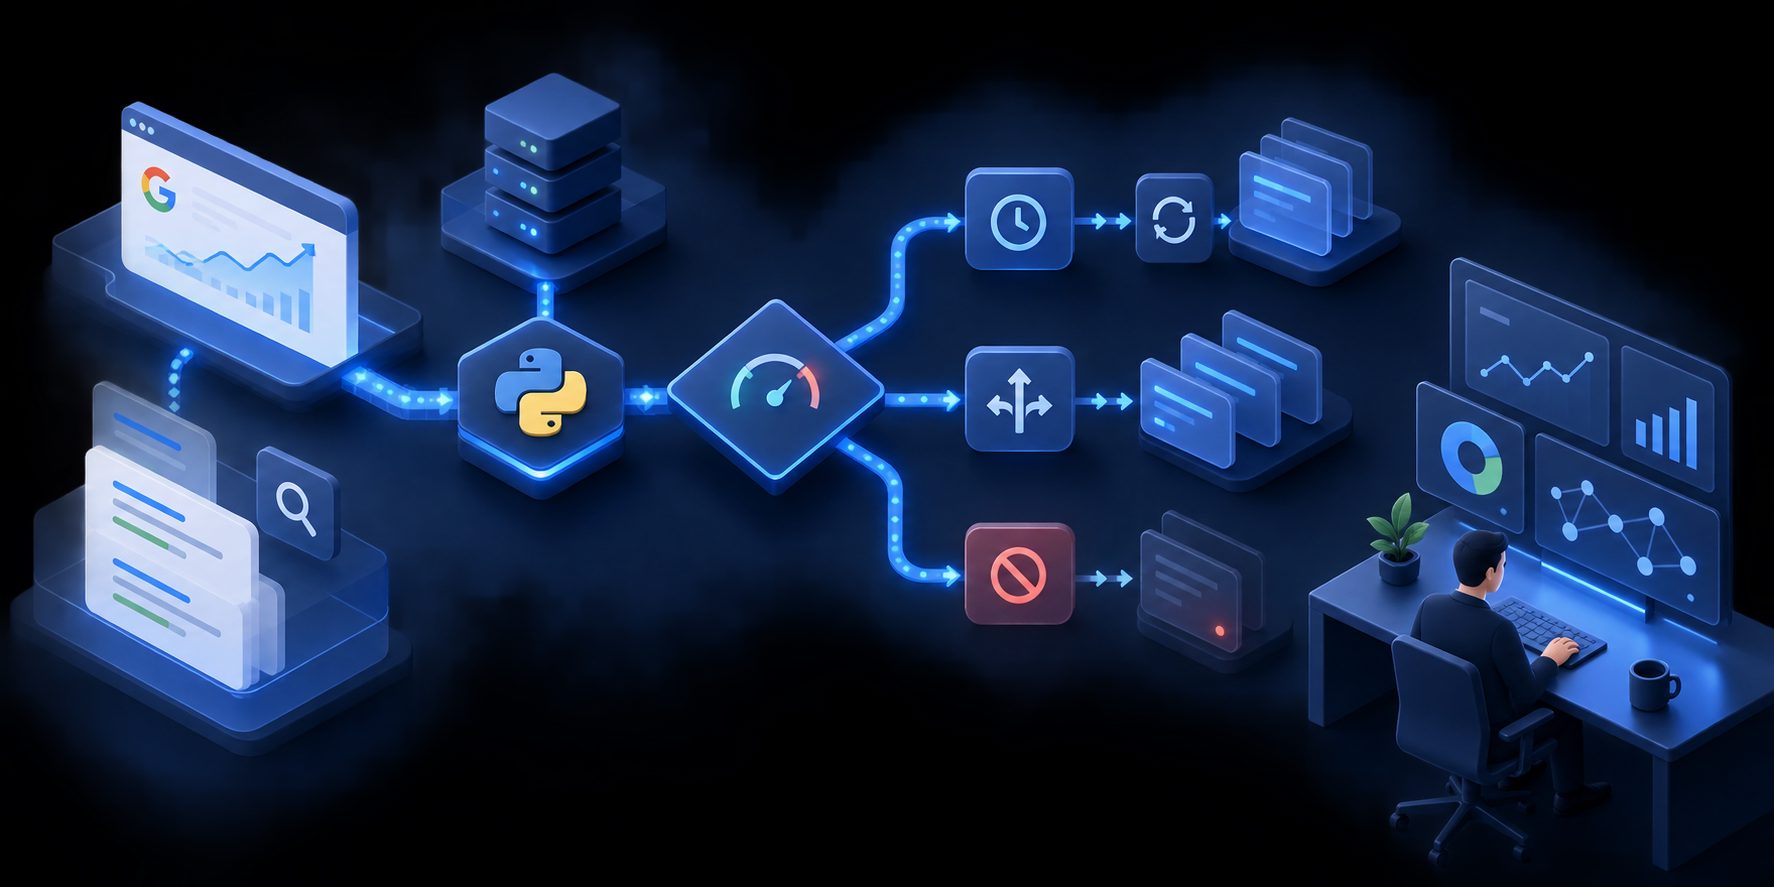
A maintainable sequence is:
- Partition extraction by property, date, and search type.
- Reserve capacity through a shared limiter.
- Execute and classify the response.
- Store raw rows and request metadata.
- Advance a durable checkpoint.
- Build reporting and SEO decisions from stored data.
That architecture also supports repeatable workflows such as automated board-level Search Console reporting without making every dashboard refresh consume API quota.
HitMind offers a free SEO audit without registration, payment, or a credit card. Signing up is free too: HitMind drafts articles from brand facts you approve and delivers them to WordPress as drafts, so nothing goes live until you press Publish.
Frequently Asked Questions
Does the Search Console API return remaining-quota headers?
Do not design the pipeline around assumed remaining-quota headers. Maintain local counters, inspect Google Cloud quota metrics where available, and treat API error reasons as the authoritative signal that a request was rejected.
What throttle should a Search Analytics script use?
For a single worker, a conservative ceiling such as 900 requests per minute leaves headroom below the published 1,200-per-minute site and user limits. Lower it when other applications share the same user, property, or project.
Should every 403 response be retried?
No. Retry only transient reasons. Permission, configuration, and daily-quota failures require intervention or a later scheduling window, not rapid repetition.
Can pagination prevent quota errors?
Pagination controls response size, not every quota dimension. It can increase the number of requests, so monitor calls per completed partition and checkpoint each page to avoid restarting from zero.
Is the Search Console API free?
Yes, Google states that the API is free, but usage quotas still apply. Performance data is also limited to 50,000 rows per day, per search type, per property. (support.google.com)