By hitmind.ai | Published 2026-10-01 | Updated 2026-10-01
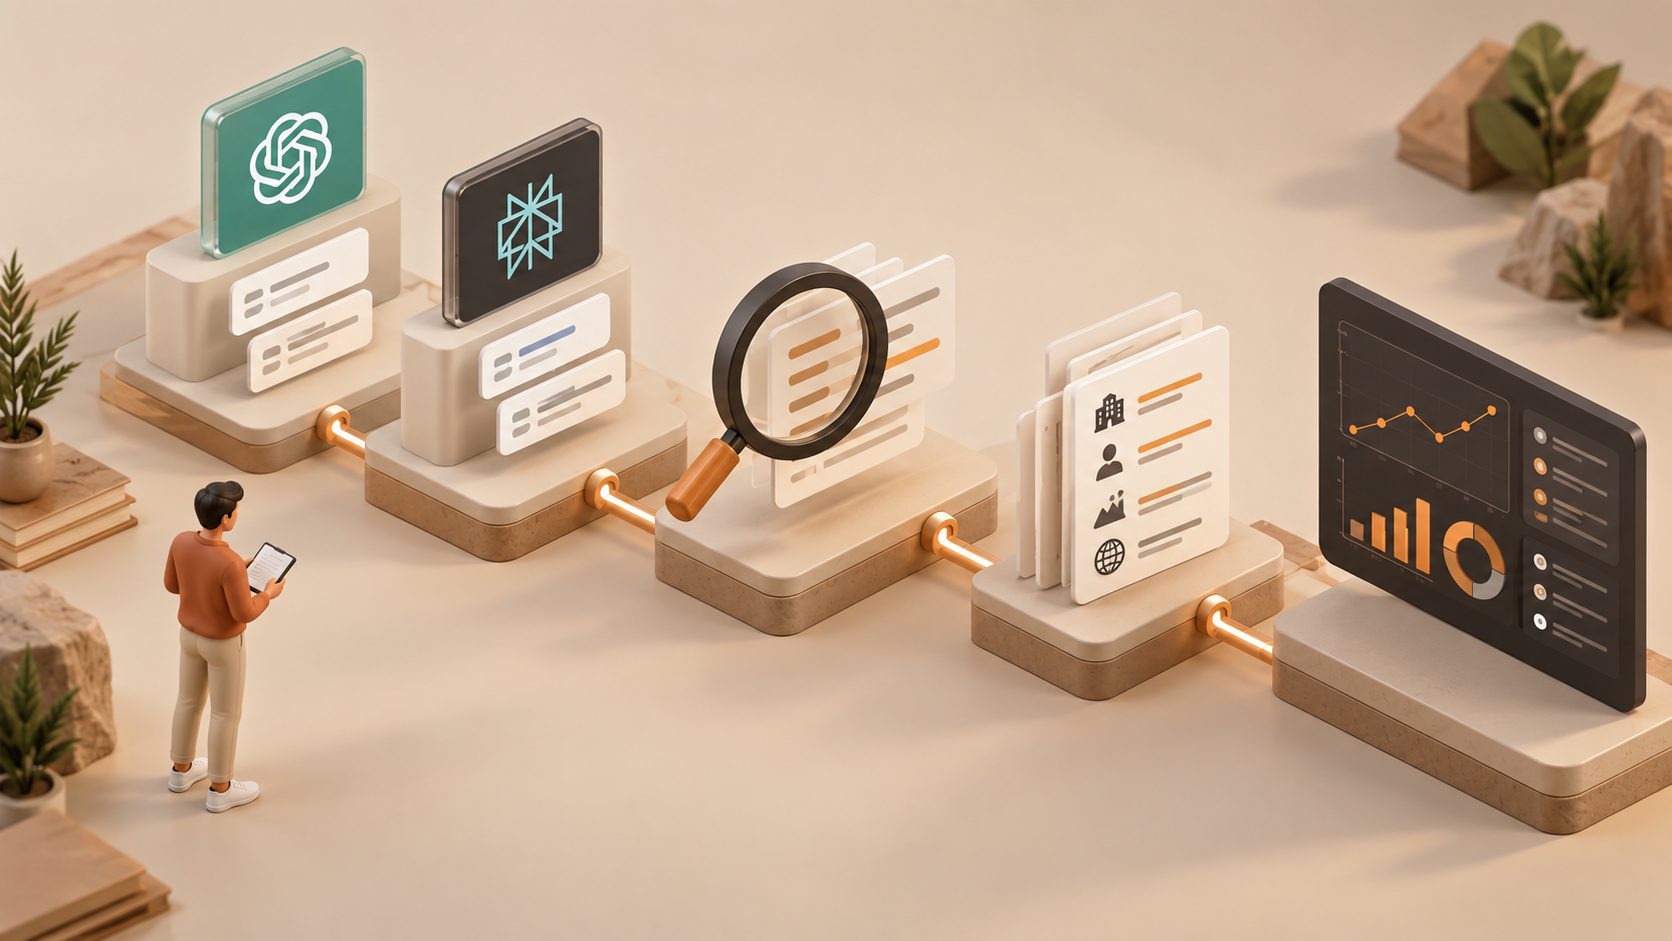
To track entity mentions across Perplexity and ChatGPT, use a fixed set of buyer prompts, repeat each test under documented conditions, and record mentions, recommendations, citations, accuracy, and competitors separately. The goal is not to capture one favorable answer. It is to build a comparable time series that reveals whether your SaaS is becoming a recognized entity.
What Counts as an Entity Mention?
An entity mention occurs when an answer identifies your company, product, founder, domain, or distinctive product category. However, a plain-text appearance is not equivalent to a recommendation or citation. SaaS teams should classify each observation before calculating visibility.
Use five mutually clear labels:
| Observation | Definition | Business meaning |
|---|---|---|
| Mention | The brand or product is named | Basic entity recognition |
| Recommendation | The answer suggests the product for a use case | Commercial preference |
| Owned citation | A page on your domain supports the answer | Traceable content visibility |
| Third-party citation | Another site discusses your entity | External corroboration |
| Accuracy issue | The answer states something false or outdated | Reputation and conversion risk |
A domain may be cited without the brand being prominently named. Conversely, a brand can appear without an owned link. Keeping these outcomes separate prevents a high mention count from hiding weak citation coverage.
For a broader measurement model, see this practical framework for brand visibility in ChatGPT answers.
Why Can the Same Prompt Produce Different Results?
ChatGPT and Perplexity generate answers rather than displaying a fixed ranking. Results can change with prompt wording, conversation history, location, selected mode, available sources, and the time of the run. A single response is therefore an observation—not a stable rank.
OpenAI explains that ChatGPT Search may rewrite a question into multiple targeted searches and use approximate location when retrieving results. Search-based responses may include inline citations or a source panel, but those sources can be incomplete or incorrect and should be checked manually. (help.openai.com)
Perplexity is more citation-forward: its search experience links answers to original sources, making cited-domain analysis especially useful. (perplexity.ai)
Research into generative-search measurement also found substantial citation variability across repeated samples. Apparent differences between domains may fall within the normal noise of the system, which makes single-run scores misleadingly precise. (arxiv.org)
How Do You Build a Repeatable Monitoring Workflow?
A dependable workflow controls the prompt set, environment, repetition, and storage format. Start manually with a spreadsheet before buying or building automation; this exposes ambiguous classifications and weak prompts while the dataset is still easy to inspect.
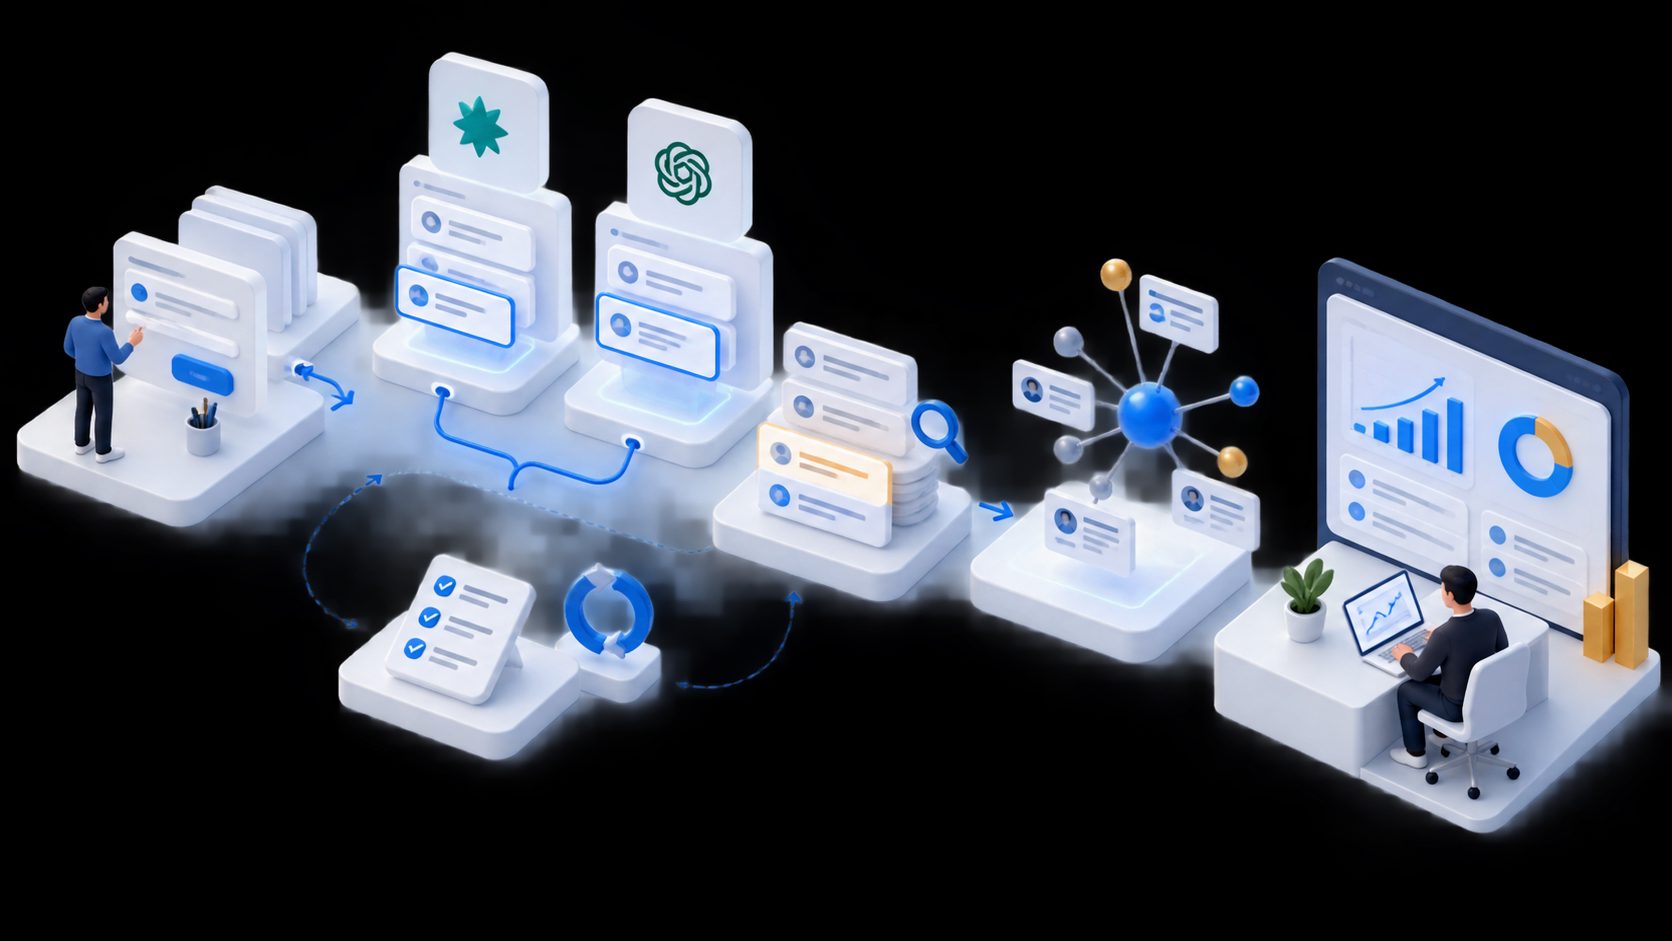
- Collect 15–30 buyer prompts. Use sales calls, support tickets, Search Console queries, community discussions, and competitor comparisons.
- Group prompts by intent. Include category discovery, use cases, comparisons, alternatives, validation questions, and branded fact checks.
- Freeze the wording. Give every prompt a permanent ID. Do not quietly rewrite prompts between reporting periods.
- Run three repetitions per engine. Start a fresh conversation for each run to reduce contamination from previous messages.
- Record the test context. Save the engine, visible model or mode, country, language, account state, date, and run number.
- Store the complete answer. A yes/no mention field is insufficient for diagnosing positioning, citations, or factual errors.
- Repeat weekly or monthly. Weekly checks suit active campaigns; monthly checks are usually adequate for directional GEO monitoring.
For prompt discovery, combine customer language with branded and non-branded Search Console query analysis rather than relying only on keyword-volume tools.
Which Metrics Should a SaaS Team Calculate?
The strongest scorecard reports visibility, preference, evidence, and reliability independently. A single composite “AI visibility score” may look convenient, but it can conceal whether progress came from repeatable recommendations, incidental mentions, or one unusually favorable response.
The following Entity Evidence Ladder is an original framework for separating those signals:
| Metric | Formula | What it reveals |
|---|---|---|
| Mention coverage | Runs mentioning entity ÷ eligible runs | Basic recognition |
| Recommendation rate | Runs recommending entity ÷ eligible runs | Buyer-facing preference |
| Owned citation rate | Runs citing your domain ÷ eligible runs | Content-source strength |
| Share of answer | Brand appearances ÷ all tracked brand appearances | Competitive presence |
| Accuracy rate | Correct brand observations ÷ brand observations | Entity understanding |
| Repeatability rate | Prompts producing the same outcome in at least 2 of 3 runs ÷ prompts | Confidence in the trend |
Report ChatGPT and Perplexity separately before combining them. For example, a high Perplexity citation rate alongside a low ChatGPT recommendation rate suggests that your pages are retrievable, but the entity may not yet be strongly associated with the buyer’s use case.
How Do You Turn Mention Data Into GEO Actions?
Every missing or inaccurate mention should become a specific content, entity, or distribution task. The monitoring sheet is valuable only when it identifies why a competitor appears, which source supports that appearance, and what evidence your site lacks.
Use this diagnosis map:
- Absent from category prompts: Create a clear category page explaining what the product is, who it serves, and where it does not fit.
- Mentioned but not recommended: Add concrete use cases, selection criteria, limitations, and comparison-ready facts.
- Recommended without an owned citation: Improve the page most capable of supporting the claim and make its answer easier to extract.
- Competitor cited repeatedly: Review the cited sources for missing topics, stronger evidence, or third-party validation.
- Wrong description or stale facts: Align homepage, documentation, profiles, and external references around consistent entity attributes.
- Strong AI mentions but weak organic demand: Compare the trend with Search Console impressions, branded queries, clicks, and landing-page behavior.
This connects AI observations to measurable search outcomes. The AI search visibility checker measurement guide explains why citations and mentions should be validated against first-party evidence instead of treated as isolated GEO wins.
When Should You Automate Entity Monitoring?
Automation becomes useful when manual collection prevents consistent sampling. It should preserve raw answers and test context—not merely output a proprietary score. Without evidence-level storage, teams cannot audit classification errors or explain a visibility change.
A useful monitoring system should support:
- Scheduled runs with locked prompts
- Separate ChatGPT and Perplexity reporting
- Multiple samples per prompt
- Full-response and cited-URL storage
- Brand alias and competitor detection
- Recommendation and sentiment classification
- Accuracy review queues
- Exportable prompt-level history
- Integration with analytics or Search Console data
Automation does not remove uncertainty. It increases sample size and operational consistency. A mature generative engine optimization workflow should connect observations to publishing decisions and then verify downstream effects with first-party data.
Frequently Asked Questions
How often should entity mentions be checked?
Use a weekly cadence during campaigns or major positioning changes and a monthly cadence for ongoing monitoring. Keep the prompt set and test conditions stable so changes are more likely to reflect visibility movement rather than a redesigned experiment.
How many prompts are needed?
Fifteen to thirty prompts can provide a practical SaaS baseline when they span category, use-case, comparison, alternative, and validation intent. A smaller set may work for a narrow product, but every important buying situation should be represented.
Can Search Console show ChatGPT or Perplexity mentions?
No. Search Console measures Google Search performance, not the generated answers inside other platforms. It can still reveal branded-query demand, landing-page impressions, and search behavior that may accompany broader entity awareness.
Is an AI mention the same as an AI citation?
No. A mention names the entity in the answer, while a citation links or attributes information to a source. Track entity mentions across Perplexity and ChatGPT separately from citations because each signal answers a different business question.
Should the results be described as rankings?
Usually not. Generated answers do not behave like a stable list of ten blue links. Use terms such as mention coverage, recommendation rate, answer prominence, citation share, and repeatability instead of assigning a precise “rank” to a variable response.